EatWhat Tonight
A pixel-art survivors-like where a slime evolves by eating — fight, snack, pick evolutions, and let AI cook up foods that exist only in your run. It is also a methodology experiment: when almost all the code is written by AI, how do you make its output trustworthy?
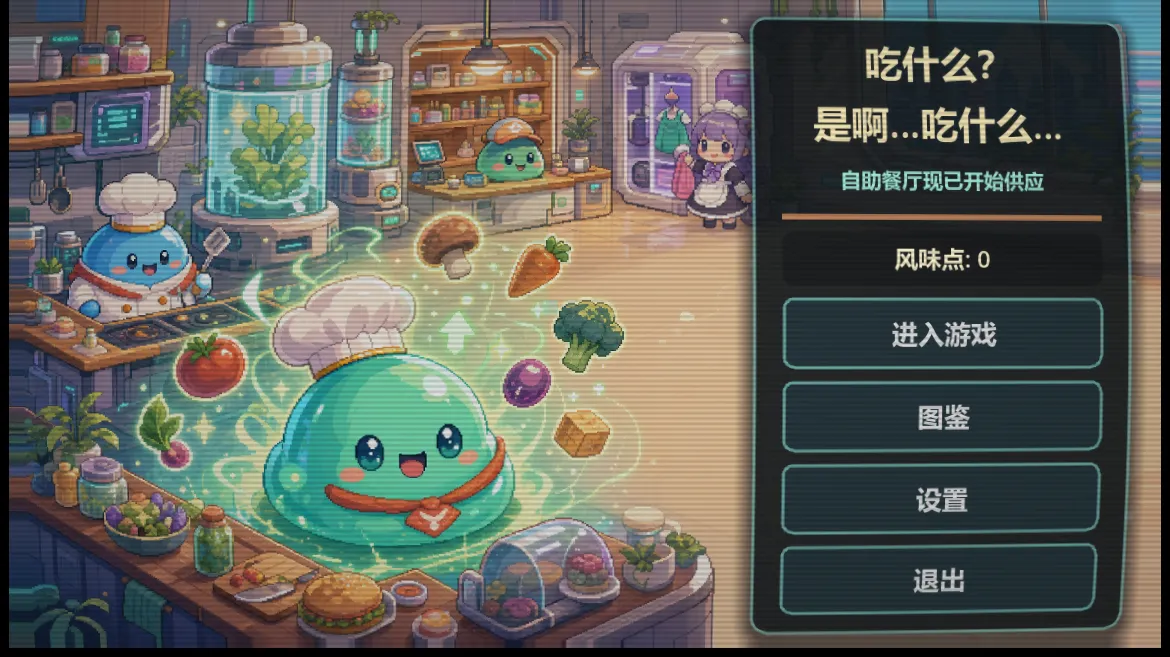
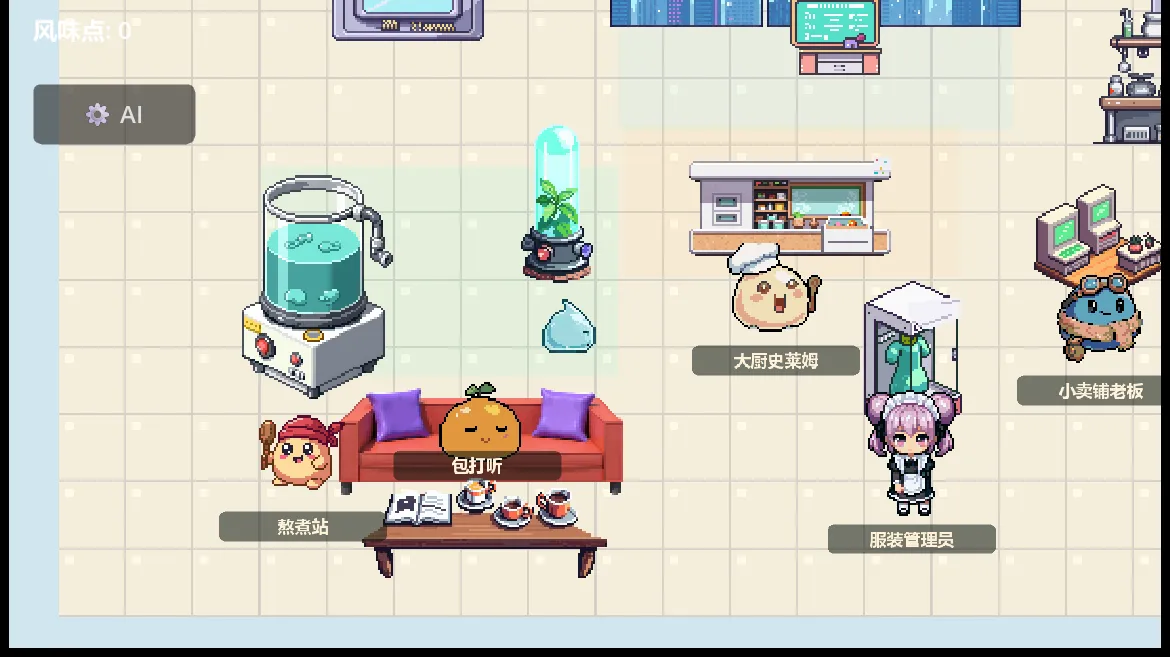
Eat to fill the evolution meter, then pick one of three cards: four branches, three tiers, plus golden combo cards on top. Win or die and you are back in the lobby, brewing looted seasonings, shopping, changing outfits, going again. Ask the chef for a dish and the game generates it on the spot — flavor text, pixel art, stats, its own evolution branch — for that run only.
I did not write this code. I specified, reviewed and accepted it.
In one line: the AI produces the work, I set the standard, find the flaws, and decide whether it ships.
The scarce skill is not producing output, it is judging it — so the engineering weight moved from how to build it to how to know it is actually right.
- A feature idea
- Write the spec first what it must and must not do · 45 docs
- Then the execution plan broken into steps · 62 docs
- Pick the collaboration mode by risk low: just do it / medium: discuss first / high: two review passes
- The AI implements
- All 129 checks must pass anything red: locate → reproduce first → then fix
- Human review
- Into the optimization log 16 batches · including what was deliberately left unfixed
Low risk     tech debt / refactors / tests        implement  →  focused verification
Medium risk  player-facing UI / feel / numbers    discuss first  →  single review
High risk    cross-module behavior / release      implement  →  spec review  →  quality review
Specs come first. I write down what is wanted before the AI touches anything. For the same feature, a vague spec buys you a version that runs but is wrong; a tight spec usually lands first try. Across dozens of iterations that is an observable, repeatable causal relationship — which is why the 45 design specs and 62 execution plans are the least code-like and most decisive part of this project.
Every trap becomes a list entry. What accumulated over a year is not a feeling that AI is useful, but a catalogue of how AI fails inside a real engine project: the symptom, the mechanism, and the rule that avoids it next time. Three of them, expandable below.
The check prints ALL OK, the verdict says FAIL
The process hangs with no output at all
Check out the repo on another machine and dozens of checks fail at once
How do you make the checks passed worth believing?
A gate here is just an automated check script: if any one of them fails, the change does not merge. This section is about making those checks tell the truth.
Code that runs is not code that is right. Three illusions sit in between: the agent reporting its own success, a local cache hiding the problem, and one retry turning red into green. A fourth is worse — nothing errors anywhere and the output is still garbage.
Only data and rules: is a field wrong, is a file missing, does the algorithm still hold, is everything wired up. Fast enough to run on every single change.
Boots the engine and runs real frames to verify systems working together: spawn counts, buff stacking, ability phases, whether the UI binds in time. Slow, but it catches what only appears once things are running.
Re-slices every real image already paid for and compares with last time: allowed to improve, never to regress. Kept separate so a missing corpus can never be the reason the suite is red.
What machines cannot judge: composition, color, readability. Honestly, this part still has no automated criteria.
| Verdict | When it is given | Blocks merge | Why it deserves its own state |
|---|---|---|---|
| TIMEOUT | still running after the timeout (180s default) | yes | A scene that fails an assertion often forgets to quit and just hangs. Without its own state it looks like it is still working |
| FAIL | a failure marker in the output (SCRIPT ERROR / FAILED / ...) | yes | The check reporting its own failure |
| ERRLOG | an engine error that is not on the whitelist | yes | Engine-level runtime errors. Before this state existed, that entire class of problem was missed |
| EXITCRASH | all assertions passed, only teardown crashed | no | The one failure whose cause is already understood — and therefore the only one allowed a single automatic retry |
| PASS | exited cleanly and printed the pass marker | no | — |
| WARN | no errors, but no pass marker either | no | Silent success is not allowed: no marker means the check may have verified nothing at all |
Four rules that got written down
None of them is generic engineering wisdom. Each is the shape this system took after reality corrected it.
Retries absorb diagnosed flakiness, nothing else
An early version retried any failure once. The suite did go green, and genuinely flaky bugs went green with it — something that reproduces 30% of the time shows as passing 91% of the time after one retry (both attempts hitting it is only 9%). So today only assertions passed, crashed on exit may be retried.
Freeze the old debt, zero-tolerance for new debt
A new rule meeting an old mess leaves two bad options: fix everything first (blocks work for weeks) or write it in a doc without checking it (no rule at all). The answer is a ratchet — like a wrench that only turns one way: freeze the existing 72 violations as a baseline and assert the total never exceeds it. Old ones do not block anyone, a new one breaks the baseline instantly, and every cleanup lowers the number for good.
CI is not a second run of what you already ran
It runs only the fastest 47 checks, and not to save time. A dev machine is full of local caches that hide problems; CI checks out from scratch, which is the equivalent of running on a machine nobody has used — missing classes and unsubmitted files only ever surface there.
Prove the gate can actually go red — in every direction
Raise the pass bar on purpose once and watch the eval report the pass rate falling from 1.000 to 0.000 and exit as a failure. A gate that has never been red is indistinguishable from a gate that does not exist. But one red run is not enough: a later audit found it missed three other ways of getting worse (end of this section). Every way a result can degrade needs its own red run — a gate you have only seen fail one way can only be trusted that one way.
The eval system needs an eval too
I went back through the real local ledgers (one row per delivery, one per review) and checked them line by line against the code. Everything I found had the same shape: it ran every time, never raised an error, and was not doing what it claimed to do.
The worst one: of the 134 rows in the delivery ledger that served as the baseline, 126 had been written by the check scripts themselves. Only 8 were real deliveries.
| Assumed | Actually | Now |
|---|---|---|
| The delivery ledger is the real baseline | 126 of 134 rows came from check scripts: check processes and the player shared one ledger, and the old test isolation only covered save files | The source is decided from launch arguments and every check writes to an isolated directory; after a full 129-check run the real ledger still has 8 rows |
| The image regression gate was proven to fire | Only for a falling pass rate. A baseline silently lowered from 1.000 to 0.893, 4 unregistered new pages, failed cells rising from 3 to 6 — all of them passed | Lowering a baseline needs a written reason and leaves history; unregistered pages fail; failed-cell counts are compared too |
| CI catches engine errors | When errors flooded the log, the old gate missed 20 runs out of 20 — exactly when it matters most | The new gate misses 0 / 20; a check now verifies that local runs and CI use the same engine version and error whitelist |
| A retry with the violation reasons lets the model fix its draft | The request was single-turn, so the model never saw its previous draft — a constrained re-roll. Hold the Line measured the same root cause: reasons alone rescued 12%, reasons plus the draft 75% | Now multi-turn, with the draft included. This path has not fired here yet; 75% is a figure from the other project and only an expectation here |
| Art deliveries are guarded | That check read a copy excluded from the build and trusted a self-reported "ok" in the QA record for pixel quality — swap the image and it stayed green | It now guards the files that actually ship and recomputes from pixels; every rule is mutation-tested: break it and the check must go red |
| Where the missed bug was | Count | Notes |
|---|---|---|
| Inside the diff | 4 | The problem was right there in the change under review |
| Outside the diff | 5 | The problem was in a file nobody touched, which a per-task review structurally cannot see. The costliest one was here: a field was deleted while another file still assigned it, so every generation threw an error at the player — and two task reports labelled it "pre-existing" |
Two AI pipelines — the hard part is acceptance, not generation
One produces art offline, the other generates a whole asset set the moment a player orders a dish. Neither is call the API and use the result — everything interesting happens afterwards: is this usable, who decides, and by what criteria?
Generate → validate → post-process → accept → ingest. Five steps, none of them skipped.
Spec before generation. A project-wide art spec first pins down the hard rules — visual direction, pixel grid, palette and values, outlines and shading, frame rates, UI type — and then, most importantly, its last two chapters: the acceptance criteria for four asset classes and exactly how to review them. Assets that fail are rejected before ingest, instead of being used because they exist.
The look has to come apart. The hero evolves several times per run, so its appearance cannot be one flat image: the character is split into fixed regions, each generated and swapped independently, with a master rig keeping every part aligned. The difficulty is not making it look good — it is getting one model output to contain several regions that are all immediately usable.
One request delivers the whole set. The player orders a dish: DeepSeek writes structured flavor text, then gpt-image-2 paints the full set into a single 1024×1024 page — one food icon plus 3 evolution branches × 3 quality tiers of parts — which is sliced and assembled locally. Why not one request per part? Because this image API bills by pixels generated, not by number of calls, so painting everything in one page is the cheapest option.
- Dish text structured JSON from DeepSeek
- Assemble the page prompt the model is forbidden to invent a background
- One 1024×1024 page 1 icon + 3 branches × 3 tiers
- Slice by pixel blobs a hard grid cut fails — the model paints off-center and splatters, so it picks the connected blob instead
- Remove the pink fringe a magenta backdrop tints white steam pink; the affected channels get pushed back
- Normalize and align
- Assemble onto the character
Turning “looks fine” into a number. An incident in August 2026: the vendor delivered and billed normally, text and abilities all succeeded, and the player still got the default template look — with nothing erroring anywhere. Three layers of failure, and not one of them was an error. Each was an absence of judgement.
- The model delivers and bills normally; text and abilities all succeed
- Slicing looks for sprites across 9 columns × 3 rows — the model painted one per branch × tier block instead
- That leaves 5 empty cells, over the threshold of 3
- The whole page is discarded fallbacks were settled per page back then
- The already-sliced food icon goes with it — the single most valuable cell of a paid delivery
- The player gets the template look, with nothing erroring anywhere the log said pipeline complete, and the NPC line blamed the vendor
| Metric | Acceptable range | Out of range means | Level |
|---|---|---|---|
| coverage · how full the cell is | 0.05 ~ 0.82 | too low: the cell is empty or just debris; too high: the backdrop was not stripped | FAIL |
| edge_touch · pixels on the cell border | ≤ 0.20 | the subject was already cut off by the neighbouring cell | FAIL |
| chroma_residue · leftover pink fringe | ≤ 0.02 | the magenta backdrop was not cleaned off the edges | FAIL |
| fragments · how many pieces | ≤ 3 | the subject shattered, or debris from a neighbour was merged in | WARN |
| center_offset · distance from center | ≤ 0.25 | the framing missed | WARN |
Degrade at a finer grain than you pay at. In that incident 5 empty cells voided the whole page, taking the already-sliced food icon with it. Now the icon and the parts settle separately, fallbacks settle per branch, and only a page where every branch failed can be dropped whole. The full page is also kept on disk forever, so the first response to a bad slice is not to buy another image but to re-slice offline with a different profile — which is exactly how the fried chicken page went from a full-page fallback to zero fallbacks, at a cost of nothing.
The whole chain is designed around failure. The model will misbehave sometimes, so every class of failure has an answer prepared in advance rather than patched in afterwards.
| What can go wrong | How it is caught |
|---|---|
| The text model writes on a dark background into the prompt, contradicting the page magenta backdrop | Background clauses are banned at generation and stripped again at assembly — which also fixes everything already cached |
| The returned JSON is polluted by code-fence noise | Strip the noise and retry, instead of declaring failure |
| A momentary network hiccup | Back off by error class: connection / DNS / TLS / 429 / 5xx are retried; timeouts are not (inference takes tens of seconds anyway, so resending only doubles the wait); 400 / 401 / 402 fail immediately, since retrying cannot help |
| It really did fail | Fall back to the signature-dish pool — crucially, signature dishes run through the same pipeline as generated ones. A fallback path that is weaker and never exercised will only invent a brand-new, untested failure when it finally fires |
| What the player sees | The chef NPC apologizes in character. The player perceives a character, not an error message |
A combination space far larger than the content volume
Four branches × three tiers of evolution, plus golden combo cards; four utensil-themed auto-weapons that can be bought and upgraded through card draws; enemies drop typed, quality-graded seasonings, the brewing station melds three into one, and shop prices combine flavor-point value with recipes. Elite affixes, theme synergies, the recipe wall and boss variants multiply against each other, so every run spans far more combinations than the raw content would suggest.
Technical implementation
Built solo in Godot 4 + GDScript, data-driven throughout.
Data-driven stages
Maps, waves, bosses, natural food and evolution pools all live in .tres resources; the Stage is just a shared skeleton — adding a stage requires almost no code.
Component combat
Characters are assembled from Health / Hitbox / Hurtbox / Mover / StatBoard components; projectile skills run through an object pool; four utensil-themed auto-weapons can be bought and upgraded through card draws.
Seasoning economy
Enemies drop typed, quality-graded seasonings; the brewing station melds three low-tier into one higher; shop prices combine flavor-point value with recipes — all implemented as pure static functions.
Everything above has a document behind it
These are documents the project actually runs on — none of them was written for a portfolio, and none was rewritten for one.
| Document | What is inside |
|---|---|
| Quality gates and the AI collaboration eval system | layered gates · the six-state verdict spec · how the noise whitelist was derived from measured frequencies · the AI failure catalogue · an audit of the eval system itself: what it found, how it was fixed, how the fix was re-verified |
| Reviewer miss-rate retrospective | two projects, 14 tasks · misses inside and outside the diff counted separately · which conclusions are inferred |
| Project-wide art remaster standards | visual direction · hard rules · acceptance criteria and review method for four asset classes |
| Release-readiness review | P0/P1/P2 triage · release gate checklist · a 30-second reproduction command for every claim |
| AIGC delivery-page quality standard | cost accounting · the five thresholds and the reasoning behind them · fringe-removal constraints · how the regression eval is used, and when a baseline may go down |
| Optimization log | 16 batches, each with how it was reproduced, how it was verified, and what was deliberately left unfixed |
One standard of judgement, two ways of producing. In the Liberty Engine ocean system it is hand-written HLSL, compute shaders and a GPU stability budget. Here it is an acceptance spec written for an AI.